Every FinOps lead and engineering manager running Qwen on Alibaba Cloud Model Studio faces the same budget question: what will each workload actually ...
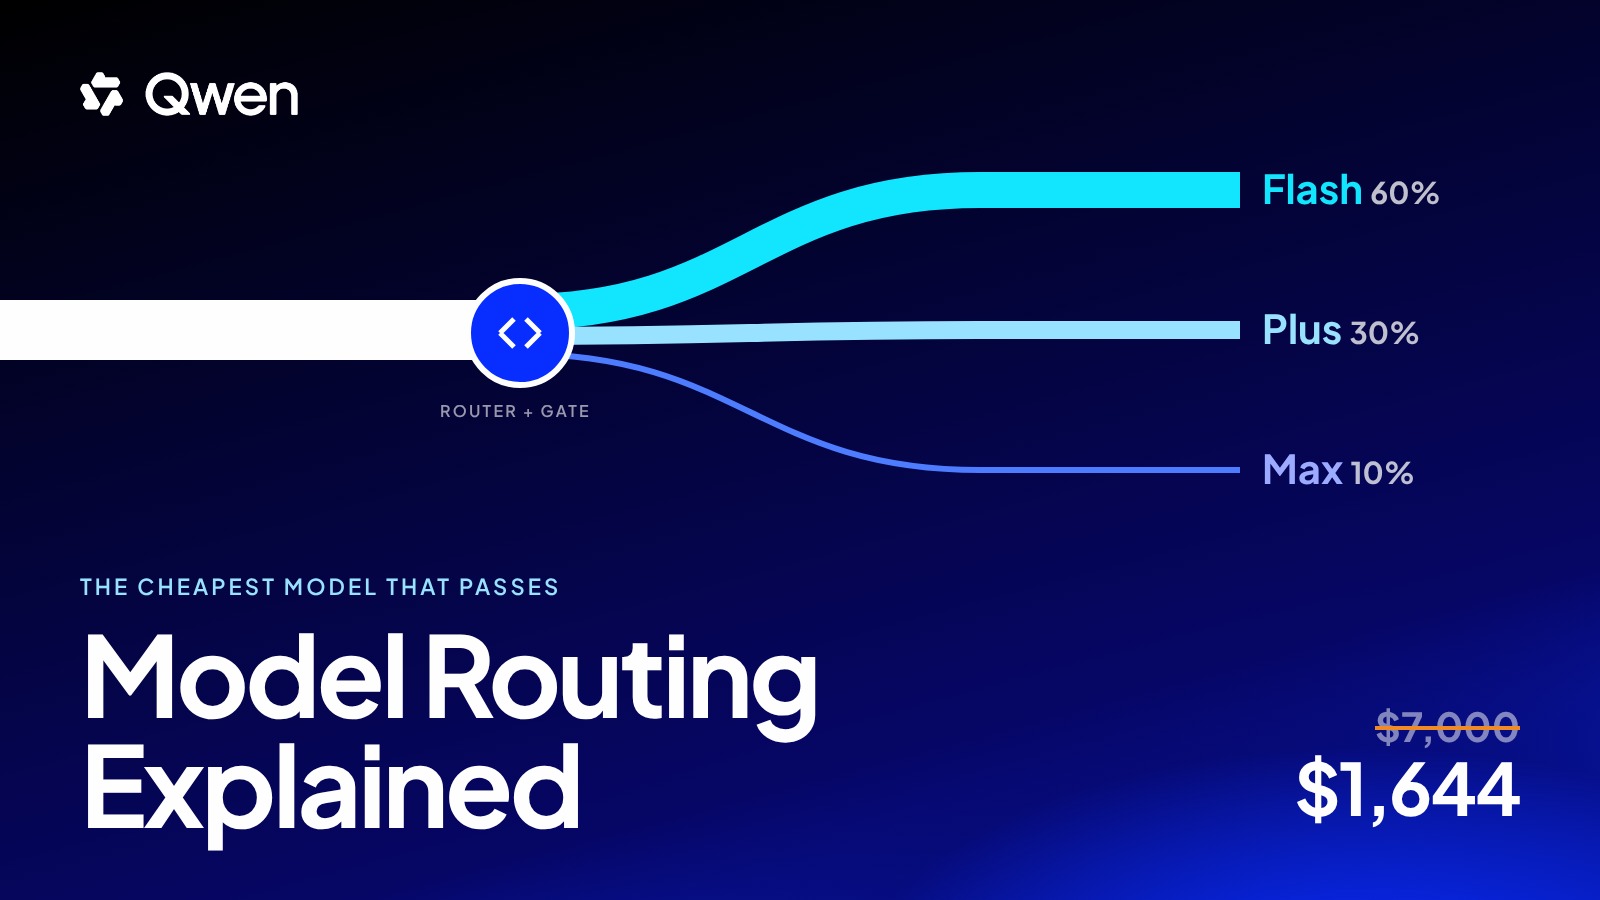
Every platform team serving Qwen at volume faces the same choice: send every request to the flagship, or route each one to the cheapest model that pas...
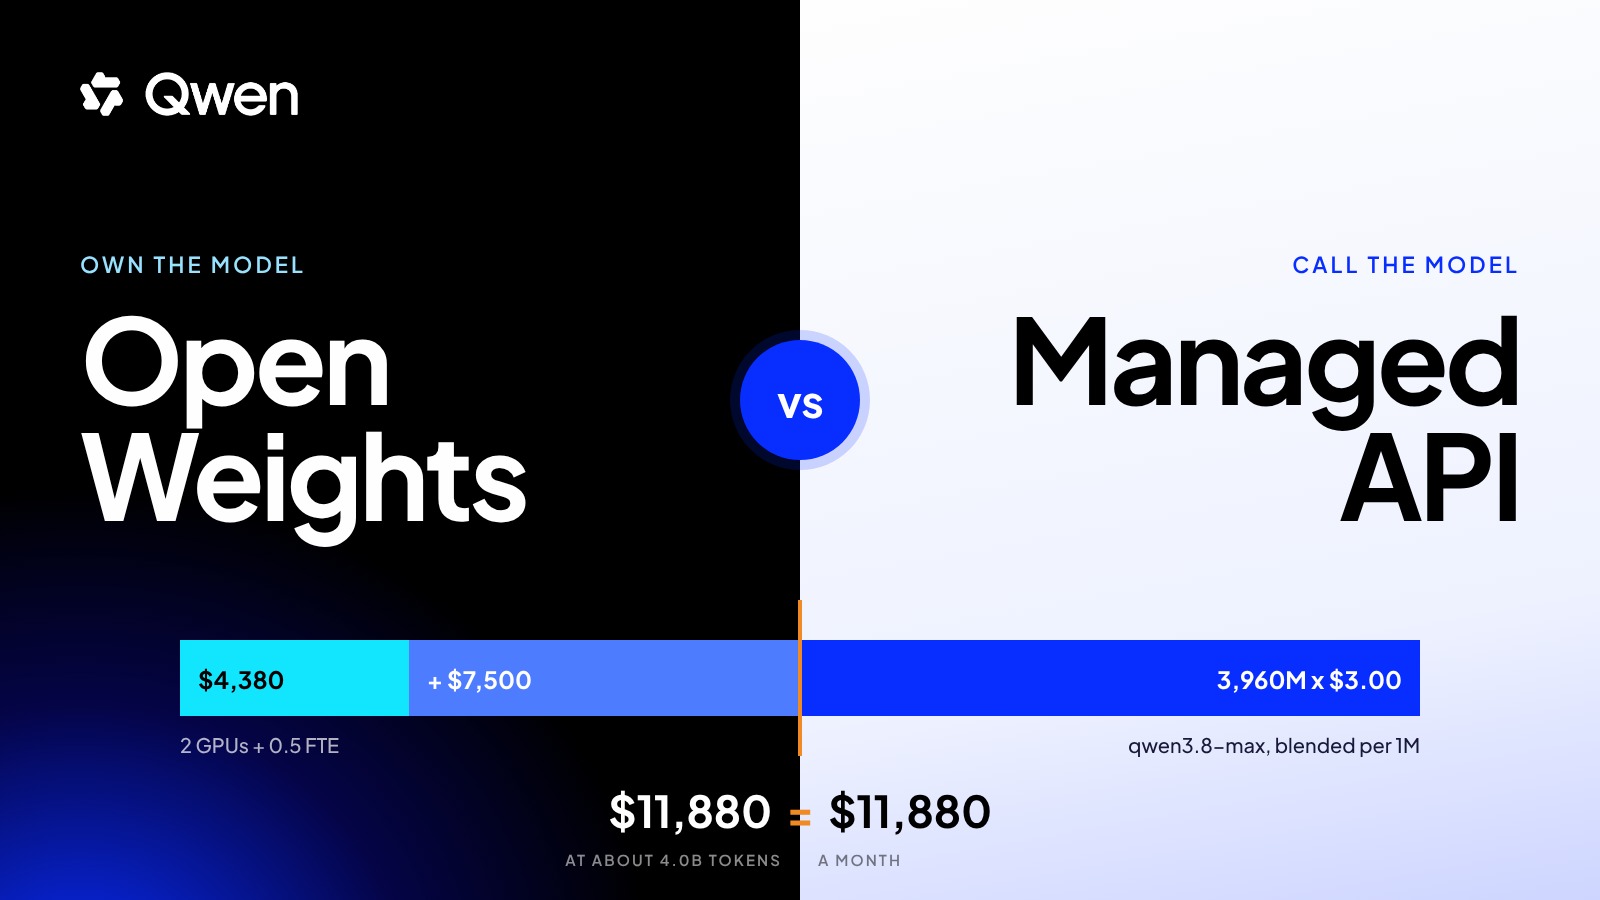
Every regulated enterprise running AI faces the same question: run Qwen open weights on infrastructure you control, or call Qwen through a managed API...
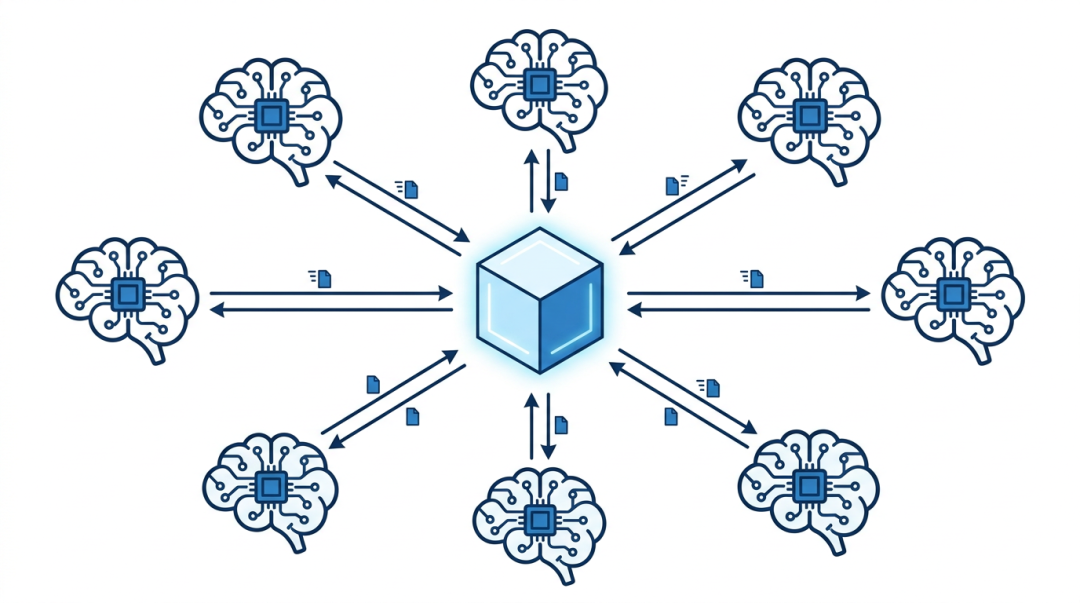
This article introduces Mooncake, a KVCache infrastructure designed to eliminate memory and latency bottlenecks in multi-agent LLM inference.
This article introduces SysOM AI Profiling, a zero-intrusion, full-lifecycle tool for diagnosing GPU performance bottlenecks and memory issues in AI workloads.
Speculative decoding accelerates large language model (LLM) inference by changing decoding from a one-token-at-a-time loop into a draft-and-verify serving pattern.
This article introduces SGLang Tracing for request-level LLM inference observability and AI agent-driven performance optimization practices.
This blog provides a practical guide to deploying and scaling generative AI applications globally using Alibaba Cloud PAI and Elastic Algorithm Service (EAS).
This article introduces Tair-KVCache-HiSim, a high-fidelity CPU-based simulator for optimizing multi-tier KV Cache configurations in LLM inference.
This article introduces hierarchical sparse attention: the full KV Cache is stored on the CPU, while the GPU keeps only a Top-k LRU Buffer.
This article introduces Alibaba Cloud’s Best Paper win at FAST 2026 for its new “Latte” local–cloud converged storage architecture and its breakthrough evolution in cloud native storage.
This article shows how SGLang RBG + Mooncake enable production-grade, cloud-native LLM inference with PD-disaggregation.
This article offers a framework for choosing between self-hosted GPUs and MaaS for LLM inference by weighing cost, data, engineering, and scalability tradeoffs.
This article introduces ACK GIE's precision-mode prefix cache-aware routing that maximizes KV-Cache hit rates for distributed LLM inference.
This article introduces how to use the cloud-native AI suite to integrate open-source inference service framework KServe and quickly deploy NVIDIA NIM in an ACK cluster.


