-
From Common Crawl to Training-Ready Corpora: Cleaning, Annotation & Vectorization with EMR Serverless Daft
EMR Serverless Daft enables end-to-end web corpus processing in a single DataFrame pipeline — from WARC extraction through cleaning, deduplication, LL...
-
-
FLIP-25: Automatic Expiration of State Data: Flink State TTL Mechanism
How Flink Manages State Data Expiration with Time-To-Live
-
-
FLIP-29: Table API Enhancements in Flink
FLIP-29: Table API Enhancements in Flink
-
-
FLIP-28 & FLIP-32: Renovating the Flink Table Building
How Flink Table Module Gets a Major Architectural Upgrade
-
-
FLIP-27: Source Interface Redesign: Building a More Efficient Data Delivery System
How Flink redesigned its Source interface to create a more efficient and manageable data ingestion system
-
-
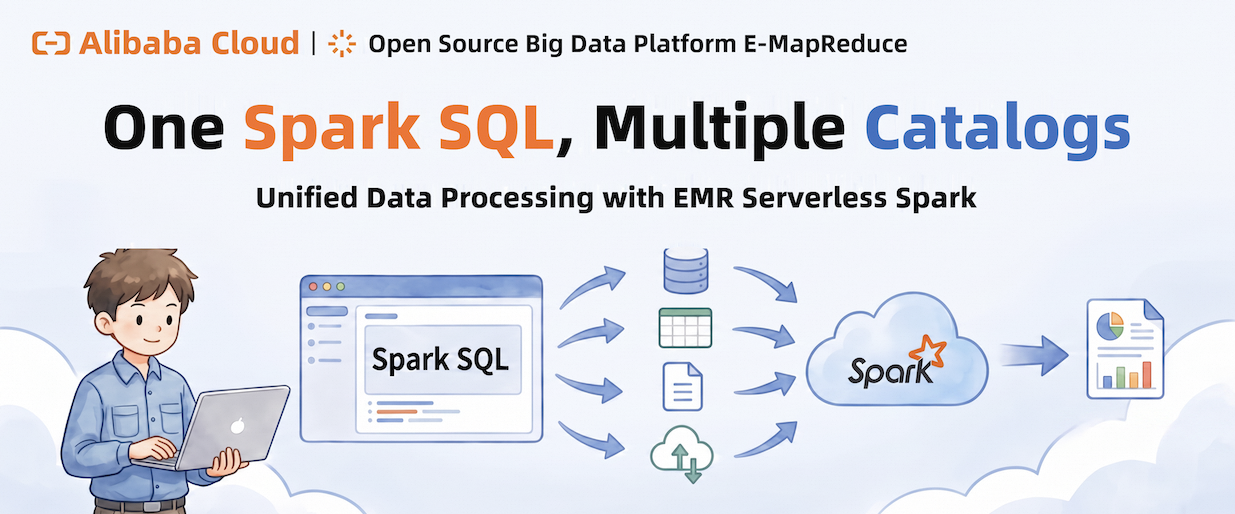
One Spark SQL, Multiple Catalogs: Unified Data Processing with EMR Serverless Spark
EMR Serverless Spark's multi-Catalog feature lets a single Spark SQL statement read, join, and write across DLF, Hive, MaxCompute, Hologres, StarRocks...
-
-
QwenWork Turns AI Agents into Practical Business Workflows
This article explores how QwenWork can support data analysis workflows by leveraging AI to examine historical datasets, identify trends and anomalies,...
-
-
Checkpoint-Based Resumption in EMR Serverless Ray Jobs
EMR Serverless Spark's Ray Data checkpoints save record-level progress so failed jobs resume from the last committed record—no reprocessing, no duplicate results.
-
-
FLIP-26: Comprehensive Security Framework for Flink
How Flink Implements a Bank-Level Security System
-
-
FLIP-24: Making SQL Easier with Flink SQL Client
How Flink SQL Client simplifies data analysis with interactive SQL interface
-
-
FLIP-22: Flink State Pre-declaration Proposal
Improving State Management with Pre-declaration in Flink
-
-
RAG Architecture Beyond Vector Search | Hologres
Learn how full-text, vector, graph, and scalar retrieval work together in a RAG architecture for complex enterprise product discovery.
-
-
How TNG Digital's Data Chief Got 400+ People to Trust the Same Number
This article introduces how TNG Digital unified its data and accelerated insights for 400+ employees using Alibaba Cloud's Quick BI for secure, self-service analytics.
-
-
For Seven Consecutive Years! Powered by Quick BI, Alibaba Cloud Has Named in the Gartner® Magic Quadrant for ABI Platforms
Powered by Quick BI, Alibaba Cloud has become the only Chinese BI vendor named in the Gartner® Magic Quadrant for Analytics and Business Intelligence .
-
-
In the AI Era, Real-Time Data Lake Ingestion Is Saying Goodbye to ETL: Architectural Subtraction from Kafka to Iceberg
This article explores how the Kafka × Table Bucket Zero-ETL architecture simplifies real-time data lake ingestion by eliminating external ETL pipelines.
-
-
FLIP-23: Unified Model Serving Platform - An Interesting but Abandoned Attempt
Understanding machine learning model deployment challenges through the lens of restaurant operations
-
-
Still Running Your Own Hive Metastore? Point Spark Straight at OSS Tables and Iceberg Just Works [OSS Tables Deep Dive]
This article explains how to connect Apache Spark directly to Alibaba Cloud OSS Tables via the Apache Iceberg REST Catalog, eliminating the need for a traditional Hive Metastore.
-
-
Still Batching Streaming Data into Files? Send Kafka Straight to the Lake with Kafka Connect [OSS Tables Deep Dive]
This article explains how to use Kafka Connect and the Iceberg Sink Connector to stream data directly from Kafka into Alibaba Cloud OSS Tables in real time.
-

-
FLIP-21: Making Objects Run Faster Between Flink Operators
How Flink Improves Object Handling in Streaming Runtime
-

-
FLIP-19: BLOB Storage Overhaul
Making File Management More Reliable in Flink
-
